Data Science Jobs in Hyderabad
Salary, Skills, Freshers & Career Guide 2026
If you are searching for data science jobs in Hyderabad, the city offers opportunities across data science and machine learning, artificial intelligence, analytics, business intelligence and data engineering. Hyderabad’s technology ecosystem includes IT, healthcare, pharmaceuticals, finance, consulting, retail and other industries.
This guide covers data science jobs in Hyderabad for freshers and experienced professionals, required skills, salary, job roles, job portals, resume tips, interview preparation and a practical career roadmap.
-
Bhanu
- No Comments
Table of Contents
Data Science Jobs in Hyderabad — Complete Guide at a Glance
Yes. Hyderabad has active opportunities for data science and related roles. Do not search only for the exact title “Data Scientist”; related titles can provide additional entry points.
| Job Role | Main Work | Key Skills | Best Entry Point For |
|---|---|---|---|
| Data Scientist | Predictive modelling and insights | Python, SQL, ML, Statistics | Candidates with strong ML and projects |
| Data Analyst | Analysis and reporting | SQL, Excel, Power BI | Freshers building analytics skills |
| ML Engineer | Build and deploy ML models | Python, ML, APIs, Cloud | Production-focused ML careers |
| AI/ML Engineer | Build AI/ML applications | Python, ML, Deep Learning | AI/ML-focused candidates |
| BI Developer | Dashboards and reporting | SQL, Power BI, Tableau | Business reporting |
| Data Engineer | Data pipelines and infrastructure | SQL, Python, ETL, Cloud | Data infrastructure careers |
| Associate Data Scientist | Analytics and modelling | Python, SQL, Statistics | Freshers and early-career candidates |
Fresher Opportunities
Freshers can enter data science through internships, associate, analyst and junior roles. Current fresher-oriented listings may ask for Python, SQL, Statistics, NumPy, Pandas, Scikit-learn and data-processing knowledge.
Core Skills to Learn
To prepare for Data Science Jobs in Hyderabad, focus on the core data science skills. The table shows what to learn and the practical outcome you should achieve.
| Core Skill | What to Learn | What You Should Be Able to Do |
|---|---|---|
| Python | Functions, data structures, NumPy, Pandas, Matplotlib, Seaborn, Scikit-learn | Load, clean, analyze and visualize data; build a basic ML model |
| SQL | SELECT, filtering, JOINs, GROUP BY, CASE, subqueries, CTEs, window functions, aggregations | Retrieve, transform and analyze data from databases |
| Statistics | Probability, distributions, variance, correlation, hypothesis testing, regression, A/B testing | Understand data patterns and support data-driven decisions |
| Pandas & NumPy | DataFrames, arrays, data manipulation, filtering and transformations | Clean, transform and analyze datasets efficiently |
| Data Cleaning | Missing values, duplicates, inconsistent data and data preprocessing | Prepare reliable datasets for analysis and machine learning |
| Data Visualization | Power BI, Tableau, Matplotlib and Seaborn | Present trends, patterns and insights clearly |
| Machine Learning | Regression, classification, decision trees, random forests, boosting, clustering, feature engineering, cross-validation and model evaluation | Select appropriate algorithms, train models and evaluate their performance |
| Git & GitHub | Version control, repositories, commits and project documentation | Maintain and showcase data science projects professionally |
| Communication | Explaining analysis, presenting findings and communicating business impact | Explain technical results in a clear, understandable way |
| Practical Projects | Real-world datasets, EDA, feature engineering, ML models and business interpretation | Demonstrate practical skills through 2–3 meaningful projects |
| Deep Learning | Neural networks and deep learning fundamentals | Strengthen your profile for AI-focused roles |
| NLP | Natural language processing concepts and applications | Work with text and language-based data |
| LLMs & Generative AI | Modern language models and AI-generation techniques | Create and understand intelligent, AI-powered solutions |
| MLOps | Model deployment and production-focused ML practices | Understand how ML models are moved toward production |
| Cloud | Cloud concepts relevant to data and ML workloads | Strengthen your profile for production-focused data and AI roles |
Key Takeaway
Start with Python, SQL, Statistics, Data Analysis and Machine Learning, then build your profile with visualization, Git/GitHub and practical projects. For AI-focused careers, add Deep Learning, NLP, LLMs & Generative AI, MLOps and Cloud based on your target role.
Salary in Hyderabad
Salary depends on experience, company, specialization and technical depth. Current Indeed data lists an average annual salary of about ₹12.62 lakh for Data Scientist roles in Hyderabad. Treat this as a market indicator rather than a guaranteed offer.
Where to Find Jobs
Use multiple sources instead of relying on one job portal:
- Naukri: Naukri
- LinkedIn Jobs: LinkedIn Jobs
- Indeed: Indeed
- Internshala: Internshala
- Instahyre: Instahyre
- Cutshort: Cutshort
- Shine: Shine
Fresher Job Strategy, Portfolio, Resume, Interviews & 90-Day Roadmap
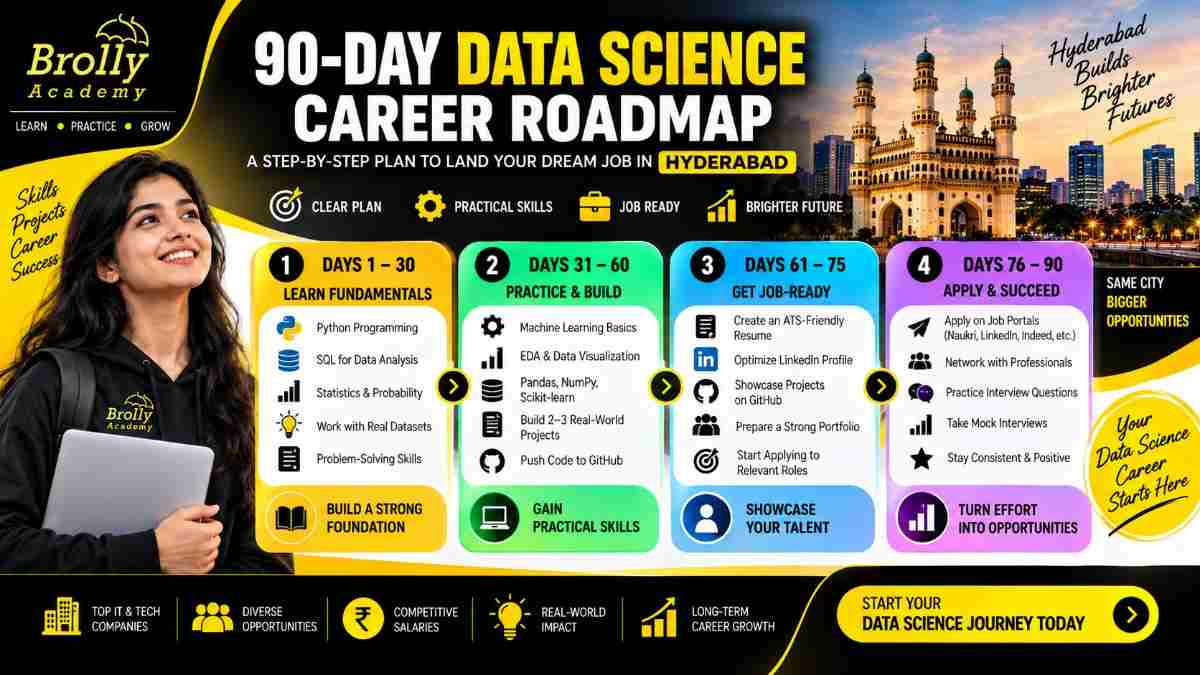
Freshers can get data science jobs without extensive professional experience when their portfolio demonstrates practical ability. Build 2–3 meaningful projects rather than many copied tutorials.
| Career Stage | Main Focus | Expected Outcome |
|---|---|---|
| Days 1–30 | Python, SQL, Statistics | Strong fundamentals and regular practice |
| Days 31–60 | ML, EDA, Visualization, Projects | 2–3 practical projects |
| Days 61–75 | Resume, LinkedIn, GitHub | Job-ready professional profiles |
| Days 76–90 | Applications, Networking, Interviews | Consistent job search and interview practice |
Build Practical Projects
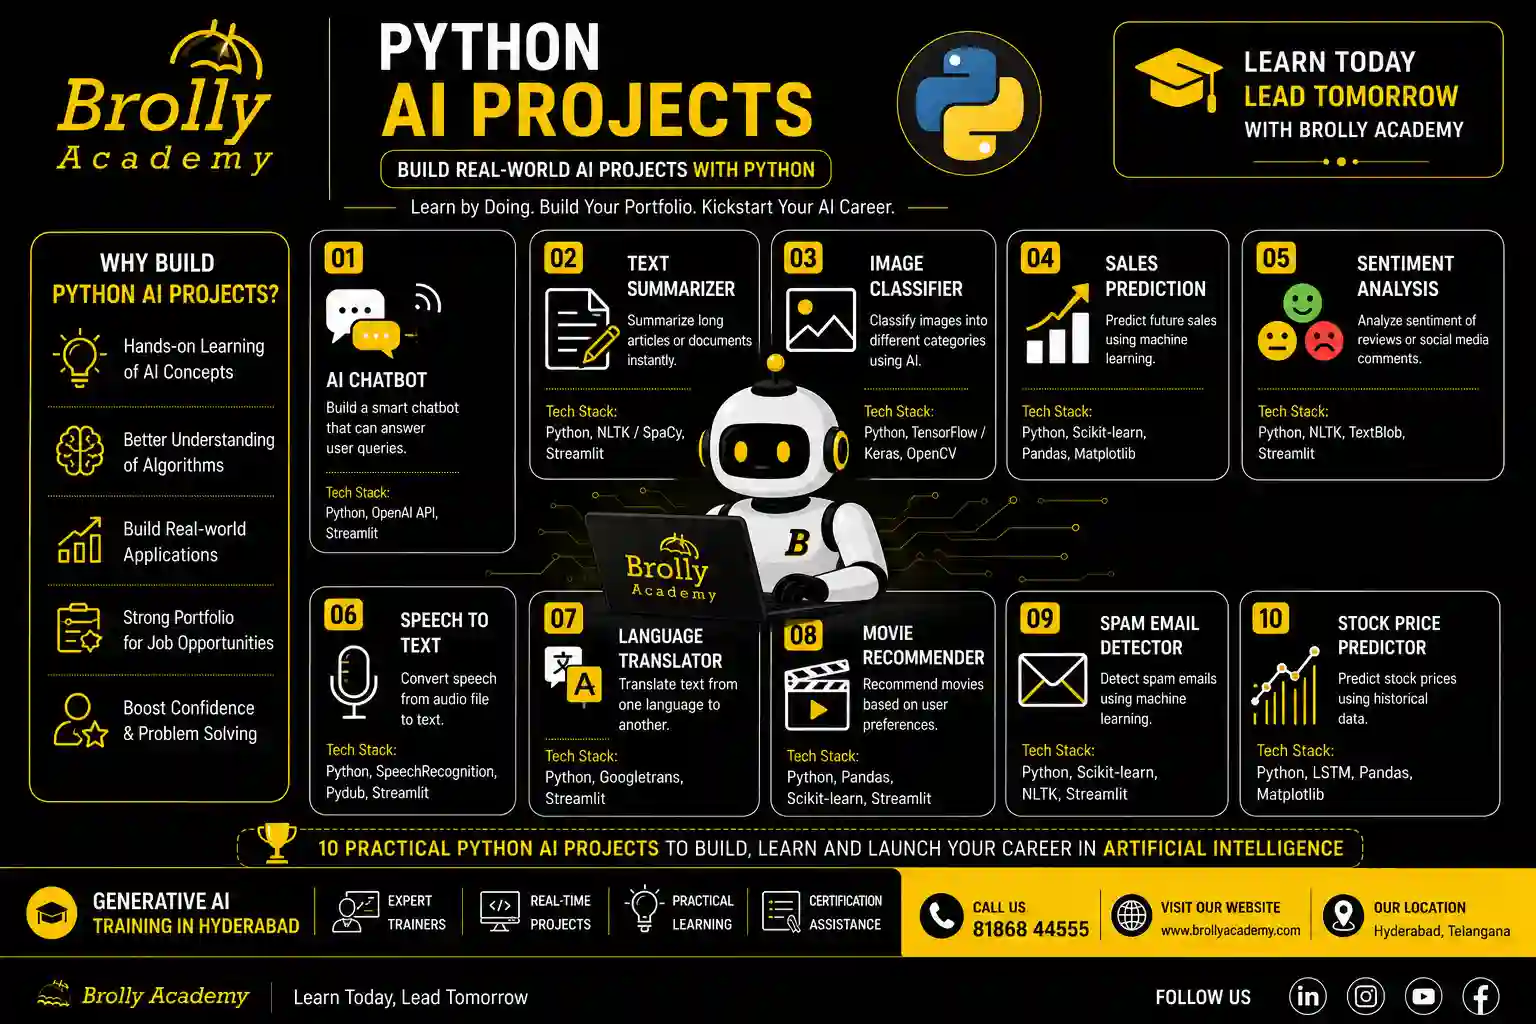
Choose realistic problems instead of copying tutorials. Useful examples include churn prediction, forecasting, fraud detection, recommendation and NLP projects.
A good project should show:
- A clear business problem
- Dataset and data source
- Data cleaning
- Exploratory analysis
- Feature engineering
- Model building
- Model evaluation
- Business interpretation
- Clear GitHub documentation
For example, a churn project should explain which customers may leave, why they may leave and what action the company could take.
Build an ATS-Friendly Resume
Keep the resume simple, one page where possible, and tailored to the target role. Highlight relevant skills and measurable project outcomes.
Instead of:
“Created a machine-learning project.”
Use:
“Developed a customer churn prediction model in Python using Scikit-learn and compared multiple classification algorithms.”
Replace vague statements with evidence. For example:
“Worked with data” → “Cleaned and analyzed customer data using Pandas and SQL to identify churn patterns.”
“Made dashboards” → “Built an interactive Power BI dashboard communicate key business metrics.”
Optimize LinkedIn
Use a clear headline such as:
Data Science Expertise | Python | SQL | Machine Learning | Statistics
Add relevant skills, projects and portfolio links.
Apply to Related Roles
Do not search only for “Data Scientist.” Also search for:
- Associate Data Scientist
- Junior Data Scientist
- Data Analyst
- ML Engineer
- AI/ML Engineer
- Analytics Associate
- Research Associate
- Data Science Intern
Related roles can provide additional entry points and useful experience for a future data science transition.
Interview Preparation
Prepare for three major areas:
Technical: Python, SQL, Statistics, Machine Learning, Pandas and scikit-learn model evaluation.
Case studies: Translate a business problem into a data problem before choosing an algorithm.
Project questions: Be ready to explain algorithm choice, missing data, evaluation metrics, overfitting, trade-offs and results.
A strong candidate should explain business impact, not only technical terminology.
Common Mistakes to Avoid
- Applying without reading the job description
- Listing skills you cannot demonstrate
- Copying projects you cannot explain
- Using the same resume for every job
- Preparing only theory
- Applying only for Data Scientist titles
- Having no portfolio evidence
- Ignoring communication skills
Which Data Role Should You Target?
| If You Enjoy… | Consider… | Prioritize… |
|---|---|---|
| Dashboards and business reports | Data Analyst / BI Developer | SQL, Excel, Power BI/Tableau |
| Building prediction models | Data Scientist | Python, Statistics, ML, SQL |
| Deploying ML systems | ML Engineer | Python, ML, APIs, Cloud |
| Building AI applications | AI/ML Engineer | Python, ML, Deep Learning, GenAI |
| Building data pipelines | Data Engineer | SQL, Python, ETL, Cloud |
| Starting with limited experience | Data Analyst / Associate Data Scientist / Intern | Python, SQL, Statistics, Projects |
Quick Action Plan
- Choose 2–3 target job titles.
- Compare their job descriptions and identify repeated skills.
- Strengthen Python, SQL and Statistics fundamentals.
- Build 2–3 practical projects aligned with those roles.
- Document the projects clearly on GitHub.
- Create an ATS-friendly resume tailored to each role.
- Optimize your LinkedIn profile.
- Set job alerts using multiple job titles.
- Apply consistently while networking with relevant professionals.
- Prepare for Python, SQL, ML, project and business-case interviews.
- Track feedback and improve weak areas.
Why This Guide Is More Useful Than a Job-Listing Page
Most job-board pages primarily display vacancies. This guide also helps users understand Hyderabad’s market, related job titles, skills, salary, fresher strategy, portfolio projects, ATS resume optimization, interview preparation, common mistakes and a 90-day roadmap.
The goal is to help a reader move from learning to employment, not simply collect data science certificates.
FAQ’s
Conclusion
Data science offers multiple career paths in Hyderabad, from Data Analyst and BI Developer roles to Data Scientist, ML Engineer, AI/ML Engineer, and Data Engineer positions. Choosing the right path depends on your skills, interests, and long-term career goals rather than simply focusing on the highest-paying role.
For freshers, building a strong foundation in Python, SQL, statistics, data visualization, and machine learning is an important first step. However, learning these skills becomes more valuable when combined with practical projects, real-world problem-solving, resume preparation, GitHub development, and interview practice.
At Brolly Academy, we focus on helping learners turn these skills into practical, job-ready capabilities through hands-on training, real-world projects, structured learning, certification guidance, and 100% Placement Assistance. Whether you are a fresher starting from the basics or looking to transition into a data science career, our goal is to provide the guidance and practical exposure needed to move confidently toward your career objectives.
If you are planning to build your data science career in Hyderabad, choosing the right learning path and getting consistent hands-on experience can make a meaningful difference. Brolly Academy is here to support you from learning the fundamentals to becoming job-ready and pursuing the right career opportunities in data science.
Brolly Academy Team
AI, Data Science & Software Training Experts | 20+ Years of Training Experience
Brolly Academy Team is a group of AI, Data Science, Cloud Computing, and Software Development professionals dedicated to helping learners gain practical skills and industry knowledge. Since 2015, Brolly Academy has supported thousands of students and professionals through technology training, certification guidance, and career-focused learning.