PYSPARK · SPARK SQL · DATABRICKS
Apache Spark Training in Hyderabad
Learn Spark Core, Spark SQL, PySpark, Scala, Spark Streaming with Kafka, MLlib and Databricks in a 30-day program with real-time big data projects and placement assistance. Classroom and live online batches, easy EMI and a free demo class before you enrol.
★ 4+ Google rating from 100+ reviews · 9,000+ students trained · 523+ batches completed · Teaching since 2021
Trainer: Mr. Venkatesh, Big Data and Apache Spark Specialist (12+ years) · Updated September 2026
TrainerMr. Venkatesh · 12+ years
Duration30 days
FeesFrom ₹9,999 · EMI
ModesClassroom + online
Apache Spark Course in Hyderabad
Brolly Academy's Apache Spark Training in Hyderabad is a 30-day, hands-on program in Spark Core, RDDs and DataFrames, Spark SQL and Hive, PySpark and Scala, Spark Streaming with Kafka, MLlib and Databricks, taught by Mr. Venkatesh (12+ years in big data, Apache Spark and data engineering). Plans start at ₹9,999, classes run in the classroom or live online, and every student gets a course completion certificate and placement assistance.
The course is built for students, freshers, developers, analysts and working professionals who want to move into big data and data engineering. You practise on local and cluster environments, build distributed ETL and streaming pipelines on Hadoop and Databricks, deploy a capstone to the cloud, and finish with a Spark-focused resume, mock interviews and interview preparation for Spark developer and data engineer roles in Hitech City, Madhapur and Kukatpally.
Why choose Brolly Academy for Apache Spark training?
Training and support✓ Industry-ready curriculum for real-time data processing
✓ Trainer Mr. Venkatesh with 12+ years in big data and Spark
✓ Hands-on projects on Spark Core, SQL, Streaming and PySpark
✓ Databricks and Hadoop ecosystem practice
✓ One-to-one mentorship with career guidance
✓ Real-time capstone projects on Hadoop and Spark
✓ Resume building, LinkedIn optimisation and mock interviews
✓ Placement assistance for data engineering roles
Flexibility and value✓ Classroom and live online batches
✓ Weekday, weekend and fast-track batch options
✓ Free demo class before you enrol
✓ Affordable fees with flexible EMI
✓ Updated content covering recent Spark versions
✓ Group learning on WhatsApp and Discord
✓ Brolly Academy course completion certificate
✓ 4+ Google rating from 100+ reviews
Apache Spark Course Syllabus (15 Modules)
Our Apache Spark training in Hyderabad follows a 15-module syllabus that takes you from the Hadoop platform and Scala basics to Spark Core, RDDs, DataFrames, the Spark ecosystem, running and tuning applications, and data analysis with Spark SQL and HiveQL.
Module 1: Introduction to Apache Spark
The Spark and Hadoop platform, overviews of Apache Hadoop and Apache Spark, data locality, ingestion and storage, analysis and exploration, and other ecosystem tools.
Module 2: Introduction to Scala
Functional vs object-oriented programming, Scala as a scalable language, Scala vs Java and basics, running programs with the Scala compiler, the type lattice and type inference, and methods and pattern matching.
Module 3: Hadoop Ecosystem Installation
Linux (Ubuntu) installation on VMware Player, installing Hadoop, and installing Apache Spark, JDK 8, Scala and SBT.
Module 4: Apache Hadoop File Storage
Why HDFS is needed, Hadoop cluster components, HDFS architecture, the failures of HDFS 1.0, reading and writing data in HDFS, and fault tolerance.
Module 5: Spark Environment
Configuring Apache Spark for development and practice.
Module 6: Scala Environment
Scala setup on Windows and UNIX, Java setup, the Scala editor, interpreter and compiler.
Module 7: In-depth Scala Core
Benefits of Scala, type inference, variables, functions and loops, control structures, vals, arrays, lists, tuples, sets and maps, traits and mixins, classes and objects, first-class functions, closures, inheritance, case classes, pattern matching, exception handling and file operations.
Module 8: In-depth Spark Core
Batch vs real-time processing, Spark vs Hadoop, Spark architecture, coding Spark jobs in Scala, the Spark shell and SparkContext, RDD programming, transformations and actions, loading and saving data, and key-value pair RDDs.
Module 9: Spark Ecosystem
Spark Streaming, MLlib, GraphX and Spark SQL.
Module 10: Apache Spark Basics
What Apache Spark is, starting the Spark shell, getting started with Datasets and DataFrames, DataFrame operations, and Spark architecture.
Module 11: RDD & Paired RDD
RDD overview and data sources, creating and saving RDDs, RDD operations, transformations and actions, converting between RDDs and DataFrames, key-value pair RDDs and map-reduce operations.
Module 12: Transform, Stage & Store
Spark documentation, initialising a Spark job, creating RDDs, previewing data, map and flatMap transformations, filtering data, and inner and outer joins.
Module 13: Running Apache Spark Applications
Writing, building and running a Spark application, deployment modes, the Spark application web UI, and configuring application properties.
Module 14: Distributed Processing
RDD partitions, stages and tasks, job execution planning, DataFrame and Dataset persistence, storage levels, viewing persisted RDDs, and RDD vs DataFrame vs Dataset.
Module 15: Data Analysis with Spark SQL or HiveQL
Interfaces for running Hive queries, creating Hive tables and loading data in text and ORC formats, and running Hive queries from the Spark shell.
Get the full Apache Spark syllabus and fee details on WhatsApp
Send us a message and we will share the complete module list, fee plans, EMI options and the next batch dates. New batches start every week, and a free demo class is available.
Apache Spark Training Roadmap – Beginner to Advanced in 30 Days
Our Apache Spark training is split into 4 practical weeks over 30 days, in the classroom or live online, with assignments and live projects that simulate real data engineering work.
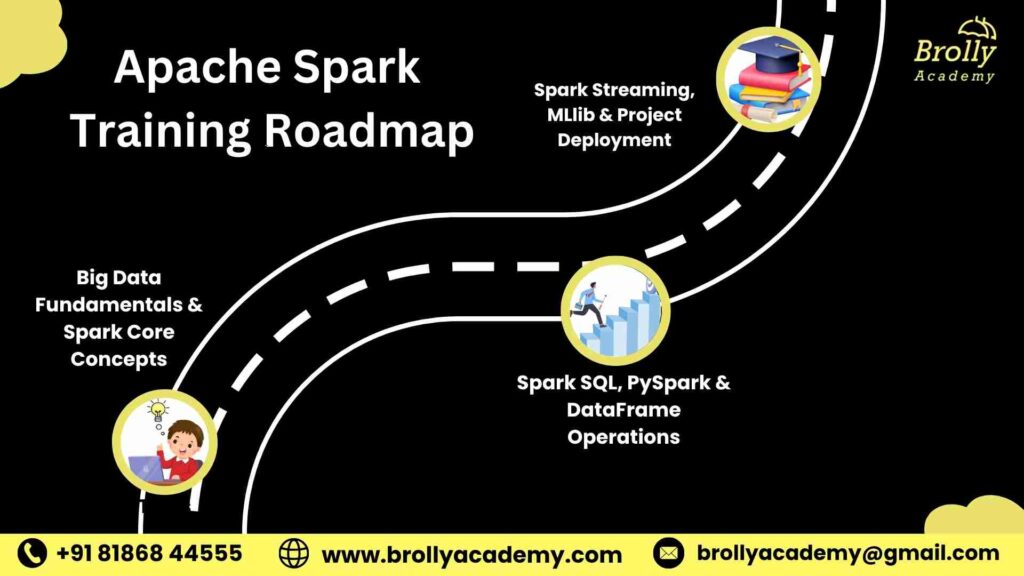
Week 1Big data fundamentals & Spark CoreThe big data ecosystem, Hadoop vs Spark, Spark architecture, RDDs, transformations and actions, partitioning and fault tolerance.
Week 2Spark SQL, PySpark & DataFramesSpark SQL, PySpark and DataFrame APIs, Hive and JDBC, ETL pipelines, the Catalyst optimiser, Tungsten and tuning.
Week 3Streaming & machine learningSpark Streaming and Structured Streaming with Kafka, Flume and HDFS, and machine learning models with Spark MLlib.
Week 4Databricks, capstone & placementDatabricks notebooks and Delta Lake, an end-to-end capstone deployed on AWS, Azure or GCP, resume sessions and mock interviews.
What is Apache Spark and Why Is It Important?
Apache Spark is an open-source, unified engine for large-scale data processing, maintained by the Apache Software Foundation. It runs jobs in memory across a cluster, handles both batch and real-time data, and offers APIs in Scala, Python and Java, which makes it a core tool for ETL, analytics, machine learning and data engineering.
Unified engineOne framework for batch, streaming, SQL and machine learning workloads.
In-memory speedRuns large data jobs in memory for fast processing.
Batch & real-timeHandles both scheduled batch jobs and live data streams.
Cluster processingProcesses massive datasets across many machines.
Multiple languagesBuilt on Scala, with APIs for Python (PySpark) and Java.
Fault toleranceRDDs recover data automatically when a node fails.
Spark SQLRun SQL queries on large structured datasets.
MLlib & GraphXScalable machine learning and graph-based computing.
Ecosystem fitIntegrates with Hadoop, Hive, Kafka and cloud platforms.
Benefits of the Apache Spark Training in Hyderabad
Choose classroom or live online training at Brolly Academy and get the same experienced trainer, real-world data processing tasks and placement support in either mode.
01Learn from an experienced trainerStep-by-step teaching from a professional with years of big data and Spark work.
02Master Spark componentsSpark Core, Spark SQL, Streaming, PySpark and MLlib with real-time practice.
03Work on real projectsEnd-to-end data pipelines using Databricks and Hadoop.
04Get job assistanceResume building, interview preparation and placement referrals.
05Understand distributed computingRDDs, partitions, fault tolerance and cluster management.
06Learn PySpark & ScalaBuild Spark applications in both Python and Scala.
07Hands-on Spark SQLQuery structured and semi-structured data with Spark SQL and DataFrames.
08Cloud & Hadoop integrationWork with AWS, Azure and Hadoop for cloud data analytics and storage.
09Learn your wayWeekday, weekend or fast-track batches, online or offline, with EMI plans.
Thinking of Apache Spark Training in Hyderabad?
Here is how hands-on training at Brolly Academy compares with a traditional class.
Traditional training✗ You sit through theory with limited practice
✗ Outdated slides and older Spark materials
✗ Trainers with only general technical knowledge
✗ Occasional lab work, mostly theory
✗ No support after course completion
✗ Small exercises with no real-world impact
✗ Limited or no placement assistance
✗ One-size-fits-all teaching for every learner
Brolly Academy training✓ Real-time Apache Spark projects from day one
✓ Recent Spark versions, PySpark and Databricks
✓ Trainer Mr. Venkatesh with 12+ years of big data experience
✓ Daily practice with Spark Core, SQL and Streaming
✓ Placement guidance through the hiring process
✓ Big data projects added to your portfolio
✓ Resume preparation, LinkedIn optimisation and mock interviews
✓ Mentorship based on your career goals
Meet Your Apache Spark Trainer
INSTRUCTOR
Mr. Venkatesh
Big Data & Apache Spark Specialist · 12+ years in big data, Apache Spark and data engineering
Mr. Venkatesh is a big data and Apache Spark specialist with 12+ years of experience in big data, Spark and data engineering. His expertise covers Spark Core, Spark SQL, Spark Streaming, PySpark, Databricks, Hadoop and MLlib. He has implemented end-to-end data processing pipelines with Spark on AWS and Azure, optimised ETL workflows and developed real-time streaming applications for enterprise clients. His teaching is practical and hands-on, using real datasets and projects to make distributed computing concepts simple for every learner.
Skills You’ll Gain from the Apache Spark Training
Distributed pipelinesBuild and manage distributed data pipelines with Apache Spark.
Spark Core, SQL & StreamingProcess batch and real-time data in one unified framework.
PySpark & ScalaWrite Spark applications with the Python and Scala APIs.
ETL on any dataTransform structured and unstructured datasets efficiently.
RDDs, DataFrames & DatasetsChoose the right abstraction for each job.
Ecosystem integrationConnect Spark with Hadoop, Hive, Kafka and HDFS.
Machine learningImplement ML workflows with Spark MLlib.
Performance tuningOptimise jobs with partitioning, caching, monitoring and log analysis.
Cloud deploymentRun Spark on Databricks, AWS EMR and Azure HDInsight.
Apache Spark Capstone Projects
You build industry-level projects that show employers how you handle large datasets and distributed processing, for data engineer, big data developer and Spark analyst roles.
Project 1Real-time streaming with KafkaA streaming pipeline with Apache Kafka and Spark Structured Streaming for finance, IoT or telecom data.
Project 2ETL pipeline with Spark & HadoopEnd-to-end ingestion, transformation and loading with Spark Core and Spark SQL on HDFS and Hive.
Project 3Customer behaviour analyticsTrends, churn patterns and segmentation from e-commerce or retail data with PySpark DataFrames.
Project 4Predictive maintenance with MLlibModels that forecast equipment failure from sensor data.
Project 5Log data analysis on DatabricksA scalable log analytics system that detects anomalies and monitors performance.
Project 6Cloud capstone deploymentAn end-to-end Spark project deployed on AWS, Azure or GCP.
Tools you use: Apache Spark · PySpark · Scala · Spark SQL · MLlib · Hadoop (HDFS) · Hive · Kafka · Flume · Databricks · Apache Airflow · Git & GitHub · Jupyter Notebook
Apache Spark Training Fee & Offerings in Hyderabad
Choose the plan that suits how you learn. Every plan covers the Apache Spark modules with project work, resume and interview support.
Video Recording₹9,999Was ₹15,000
All Spark modules (Core, SQL, Streaming, PySpark, MLlib)
60+ recorded classes
Lifetime video access
1 capstone project
Resume and interview preparation support
Placement assistance
WhatsApp support group
Most popularClassroom Training₹29,999Was ₹35,000
30-day structured classroom training with lab sessions
Trainer Mr. Venkatesh (12+ years)
Real-time projects (ETL pipelines, streaming, Databricks)
One-on-one mentorship and lab guidance
Mock interviews and project reviews
Resume building and LinkedIn optimisation
Soft skills and aptitude training
Dedicated placement officer
Commute support (offline batches)
WhatsApp support and group access
Online Course₹24,999Was ₹30,000
Live interactive classes, flexible timings
30-day program with daily recorded sessions
Real-time projects on PySpark, SQL and Streaming
Weekly mock interviews and assessments
Dedicated doubt-clearing classes
50+ interview questions and Spark assignments
WhatsApp group and trainer support
Easy EMI options are available. Ask about the current batch offer when you book your free demo class.
Placement Program for Apache Spark Training in Hyderabad
Our placement support helps you build job-ready skills and get interviews with data engineering, analytics and IT companies in Hyderabad and across India.
Resume buildingATS-friendly resumes for Apache Spark, big data and data engineering roles.
Placement trainingHow to apply, prepare for technical and HR rounds, and read hiring trends.
Interview question bankApache Spark and PySpark interview questions commonly asked by MNCs.
Internships under expertsHands-on internship work on real Spark projects with industry mentors.
Real-time projectsEnd-to-end pipelines and streaming apps with Spark, Hadoop and Databricks.
Aptitude preparationLogical reasoning, analytical skills and technical problem-solving.
Personality developmentCommunication, confidence and interview etiquette workshops.
Mock interviewsTechnical and HR sessions focused on Spark questions.
Interview schedulingWe connect you with hiring companies and support you through to an offer.
What Our Students Say About Apache Spark Training in Hyderabad
"I joined Brolly Academy for the Spark online course and it was a great experience. I enjoyed the course and learned a lot from it. The instructors were very knowledgeable and experienced in Apache Spark. I would recommend this course to anyone who wants to get started with Apache Spark."Jeenal
"The Apache Spark course at Brolly Academy is very good. They have a great training staff and the course is well organised. The instructors are experienced, knowledgeable and friendly, and they give individual attention to each student and help with their queries."Manu
"I enrolled for the Apache Spark video course and found it very helpful and easy to follow. The class recordings were clear and the instructors knew the subject well. They explained each concept so that even the toughest topics were easy to understand, and the course content is very detailed."Dexter
"Brolly Academy's Apache Spark placement assistance in Hyderabad is very useful. They prepare you with mock interviews and help with the interview process, and they gave me extra tips that helped me a lot. I would recommend Brolly Academy's Apache Spark training to anyone looking for a career in big data."Abhimanyu Samantray
Student community
Learning & collaborationWork with fellow learners on Spark projects, share code and solve challenges as a team.
Resources and toolsSpark materials, datasets, case studies and project recordings to learn at your own pace.
NetworkingConnect with data engineers, trainers and recruiters from IT companies in Hyderabad.
MentorshipGuidance from big data experts on projects, career planning and interviews.
Career developmentJob openings, internship leads and placement drives shared by our placement team.
Pre-requisites & Eligibility
A few foundational skills help you learn Apache Spark faster, but even beginners can join because every topic starts from the basics. Anyone with basic computer knowledge or a background in IT, computer science or data can enrol.
Basic programmingFamiliarity with Python, Java or Scala is recommended but not mandatory.
Databases & SQLKnowing how data is stored, queried and processed helps.
Big data basics (optional)HDFS, MapReduce or big data awareness gives a head start.
Analytical thinkingComfort with data analysis, logic building and problem-solving.
System requirementsA computer with at least 8GB RAM, stable internet and permission to install software.
Beginners welcomeThe trainer starts every topic from the basics.
Who Should Join the Apache Spark Training?
Students & fresh graduatesComputer science, IT and electronics graduates starting a career in big data.
Software developersMove from traditional programming to distributed data processing.
Data analysts & BI professionalsAnalyse large datasets faster and move into data engineering.
Hadoop, ETL & data engineersUpgrade pipelines to faster, in-memory processing with Spark.
Machine learning engineersRun large-scale model training with Spark MLlib.
IT professionals changing careersMove from testing, support or admin roles into big data and cloud analytics.
Apache Spark Career Opportunities in Hyderabad
Apache Spark developerBuild and manage Spark applications for large-scale data processing.
Big data engineerDesign ETL workflows and streaming pipelines with Spark, Hadoop and Kafka.
Data engineerHandle structured and unstructured data on AWS, Azure or GCP.
PySpark developerBuild Spark applications in Python for transformation and machine learning.
Data analyst / BI engineerRun large-scale analysis with Spark SQL and DataFrames.
Machine learning engineerBuild and deploy predictive models with Spark MLlib.
ETL / data pipeline engineerManage high-volume data integration between enterprise systems.
Big data associateEntry-level role focused on Spark Core, PySpark and SQL.
Spark architectSenior role designing ETL workflows and data architecture.
Apache Spark developer salary in Hyderabad – 2026
Junior Spark developer₹4.2–6 LPAFreshers (0–1 year) · Spark Core, PySpark and SQL
Spark developer₹6–9 LPAMid-level (1–3 years) · Spark SQL, Streaming and Hadoop
Data engineer (Spark)₹9–13 LPA3–5 years · Databricks, AWS EMR and performance tuning
Senior data engineer / Spark architect₹13–18 LPASenior (5–8 years) · ETL workflow design
Data architecture lead₹18–25 LPA+Lead (8+ years) · real-time analytics teams
Hiring companiesWhere students applyGoogle · Microsoft · TCS · Infosys · Wipro · HCLTech · Tech Mahindra · Capgemini · Accenture · Deloitte · IBM · Cognizant
Apache Spark Certification You Will Receive
After completing the training you receive a Brolly Academy Apache Spark course completion certificate that highlights your skills in Spark Core, Spark SQL, PySpark, Spark Streaming and Databricks. Classroom and online students receive the same certificate, and together with your capstone projects it strengthens your resume for data engineering and big data roles.
Vendor certification to aim for next: the course gives you a foundation for the Databricks Certified Associate Developer for Apache Spark exam (Python or Scala). It is issued and examined by Databricks, and the exam fee is separate from the course fee.
Market trends for Apache Spark in Hyderabad
Rising demandOrganisations prefer Spark over traditional Hadoop for streaming and faster analytics.
Cloud platformsAWS, Azure and GCP run Spark for scalable pipelines and Databricks workflows.
AI & data engineeringMLlib, Spark SQL and GraphX power large-scale machine learning pipelines.
Jobs across industriesFinance, healthcare, e-commerce, telecom and IT consulting need Spark skills.
Streaming analyticsReal-time data from Kafka and IoT feeds modern business dashboards.
Career flexibilityRoles for freshers, experienced developers and career switchers.
Apache Spark Training in Kukatpally, Hyderabad
Our centre is at Metro Pillar No. A689, Dr Atmaram Estates, 3rd Floor, Nizampet X Roads, near JNTU Metro Station, Hyderabad 500072. Students join from Kukatpally, KPHB Colony, JNTU, Nizampet, Miyapur, Hitech City, Madhapur and Ameerpet (a short metro ride). Can’t make it to class? Join the same course live online.
Other relevant courses
Java Full StackFront-end, back-end and databases with Java.
Python Full StackFull-stack web development with Python.
SQLQuery, join and extract data from relational databases.
Data SciencePython, statistics and machine learning for data roles.
Google Cloud (GCP)Google Cloud Platform fundamentals and data services.
AWSCloud computing on Amazon Web Services.
Apache Spark Training in Hyderabad – FAQs
1. What is the fee for Apache Spark training in Hyderabad?
Brolly Academy offers three plans: Video Recording at ₹9,999 (was ₹15,000), Online Course at ₹24,999 (was ₹30,000) and Classroom Training at ₹29,999 (was ₹35,000). Every plan covers the Spark modules with project work and resume and interview support. Flexible EMI options are available, so ask about the current offer at your free demo.
2. How long does the Apache Spark training take?
The Apache Spark training runs for 30 days. Week 1 covers big data fundamentals and Spark Core, week 2 Spark SQL, PySpark and DataFrames, week 3 streaming and MLlib, and week 4 Databricks, a cloud capstone and placement preparation. Weekday, weekend and fast-track batches are available in the classroom and online.
3. Which is the best Apache Spark training institute in Hyderabad?
Brolly Academy is a strong choice for Apache Spark training in Hyderabad. You learn from Mr. Venkatesh, who has 12+ years in big data and Spark, follow a 15-module syllabus with PySpark, Scala, Spark SQL, Streaming and Databricks, build six real-time projects, and get resume, mock interview and placement support, in class or online.
4. What topics are covered in the Apache Spark course?
The course covers the Hadoop platform and HDFS, Scala from basics to core concepts, Spark architecture, RDDs and paired RDDs, DataFrames and Datasets, Spark SQL and HiveQL, PySpark, Spark Streaming with Kafka, MLlib and GraphX, running and tuning Spark applications, distributed processing, and Databricks, with hands-on big data projects throughout.
5. What are the prerequisites for learning Apache Spark?
Basic knowledge of Python, Java or Scala and some SQL is recommended but not mandatory, because every topic starts from the basics. Awareness of HDFS or MapReduce gives you a head start. You need a computer with at least 8GB RAM and stable internet so you can install Spark, Hadoop and Databricks tools.
6. Can freshers and non-IT learners join Apache Spark training?
Yes. There are no strict admission criteria: anyone with basic computer knowledge can enrol, and graduates from computer science, IT, electronics and related fields are a natural fit. Freshers usually start as junior Spark developers or big data associates, and the course adds real projects and interview preparation for that first role.
7. What is the salary of an Apache Spark developer in Hyderabad?
Freshers typically earn around ₹4.2–6 LPA, and professionals with 1–3 years around ₹6–9 LPA. With 3–5 years and skills in Databricks, AWS EMR and tuning, pay rises to about ₹9–13 LPA, senior engineers earn ₹13–18 LPA, and leads ₹18–25 LPA or more. Actual pay depends on skills and employer.
8. Does Brolly Academy provide placement support for Apache Spark students?
Yes. Brolly Academy provides placement assistance that includes ATS-friendly resumes, LinkedIn optimisation, Spark and PySpark interview questions, aptitude preparation, personality development, mock technical and HR interviews, and interview scheduling with hiring companies in Hyderabad. Classroom students also get a dedicated placement officer, and support continues through the hiring process.
9. Will I get a certificate after the Apache Spark training?
Yes. You receive a Brolly Academy Apache Spark course completion certificate that shows your skills in Spark Core, Spark SQL, PySpark, Streaming and Databricks. The course also gives you a foundation for the Databricks Certified Associate Developer for Apache Spark exam, which is issued by Databricks; that exam fee is separate from the course fee.
10. What is the difference between online and classroom Spark training?
Both modes have the same trainer, syllabus, projects and placement support. Classroom training at our centre near JNTU Metro Station adds lab sessions and direct mentorship, while live online classes offer flexible timings with daily recorded sessions for revision. A Video Recording plan with 60+ recorded classes suits self-paced learners.
11. Which tools will I learn in the Apache Spark course?
You work with Apache Spark, PySpark, Scala, Spark SQL and MLlib, the Hadoop ecosystem with HDFS and Hive, Kafka and Flume for streaming data, Databricks and Delta Lake, Apache Airflow, Git and GitHub, and Jupyter Notebook. You also deploy a capstone project on AWS, Azure or GCP.
12. How does Apache Spark compare to Hadoop MapReduce?
Spark processes data in memory, so it is much faster than disk-based Hadoop MapReduce for most workloads. Spark also supports real-time streaming, SQL and machine learning in one framework and is easier to code and maintain. Spark still works well with Hadoop, and our course teaches HDFS and Hive alongside Spark.
13. Does the Apache Spark training include real-time projects?
Yes. You build six projects: a real-time streaming pipeline with Kafka and Structured Streaming, an ETL pipeline with Spark, HDFS and Hive, customer behaviour analytics with PySpark, predictive maintenance with MLlib, log data analysis on Databricks, and an end-to-end capstone deployed on AWS, Azure or GCP.
14. Is PySpark easier than Scala for learning Spark?
PySpark is usually easier for beginners because it uses Python syntax, while Scala is Spark’s native language and is often preferred for performance-critical projects. Our course trains you in both, so you can build Spark applications with PySpark and Scala and choose the right one for each job or employer.
15. Is there Apache Spark training near me in Kukatpally or JNTU?
Yes. Brolly Academy is at Metro Pillar No. A689, Dr Atmaram Estates, 3rd Floor, Nizampet X Roads, near JNTU Metro Station, Hyderabad 500072. Students join from Kukatpally, KPHB Colony, Nizampet, Miyapur, Hitech City, Madhapur and Ameerpet. If travel is difficult, you can join the same Apache Spark training live online.
Got more questions? Talk to our team directly
Contact us and our academic counsellor will get in touch with you shortly. A free demo class is available before you enrol.