
Snowflake Schema vs Star Schema

What is the Snowflake Schema?
The Snowflake Schema is a data modeling technique employed in the design of relational databases, particularly in the context of data warehousing. It represents a normalized form of the more familiar Star Schema, aiming to reduce redundancy and improve data integrity. In the Snowflake Schema, data is organized into a structure resembling a snowflake, with the central fact table connected to multiple dimension tables, and each dimension table further normalized into sub-dimensions.
One of the defining features of the Snowflake Schema is its emphasis on data normalization. Unlike the Star Schema, where dimension tables are denormalized, the Snowflake Schema takes the approach of breaking down dimension tables into smaller, related tables. This process involves creating a hierarchy of related tables, resulting in a structure that resembles a snowflake when visualized. Each level of normalization serves to minimize data redundancy and ensures that data is stored in a consistent and efficient manner.
What is the Star Schema?
The Star Schema is a fundamental and widely employed data modeling technique in the realm of relational databases and data warehousing. This schema design is recognized for its simplicity, efficiency, and effectiveness in organizing data for analytical purposes. At its core, the Star Schema consists of a central fact table surrounded by denormalized dimension tables, forming a structure that resembles a star when visualized.
In the Star Schema, the central fact table contains quantitative and measurable data, such as sales figures or performance metrics, forming the focal point of the schema. Surrounding this central fact table are dimension tables, each representing a specific category or aspect related to the facts. These dimension tables contain descriptive attributes that provide context and additional information about the data stored in the fact table.
Star vs Snowflake Schema: One Sales Example
A snowflake schema is a modelling pattern, not a requirement to use the Snowflake cloud product. Both patterns organise facts and dimensions. The key difference is whether a dimension stays in one wider table or is split into related tables.
First define the grain: in this example, one fact row represents one order line. The fact stores an order-line key, product key, date key, quantity and sales amount. Do not mix order totals and order-line amounts in the same measure without an explicit design.
| Design | Product dimension |
|---|---|
| Star | DimProduct holds ProductKey, ProductName, SubcategoryName and CategoryName in one table. |
| Snowflake | DimProduct links to DimSubcategory, which links to DimCategory. Each table has its own key. |
| Same analytical question | Group sales amount by category. The snowflake version follows more relationships to reach the category. |
In the star version, repeating a category name across product rows can make reporting simpler. In the snowflake version, storing that category separately can centralise its definition. Neither advantage proves that every query will be faster or every update easier.
For Power BI specifically, Microsoft's star-schema guidance explains why a single dimension table can be preferable to a snowflake dimension in the semantic model. That recommendation should not be treated as a universal benchmark for every database engine.
Test before deciding: use the same source rows, business totals and representative report queries. Compare refresh effort, query time, storage and whether users can understand the relationships. Check unique dimension keys and one-to-many relationships so a join does not multiply sales rows.
Finally, decide how product changes should affect historical reports. Overwriting a category and preserving its historical versions answer different business questions. For the upstream data flow, read our OLAP and OLTP comparison.
Advantages of Snowflake Schema in Data Warehousing
In the dynamic landscape of data warehousing, selecting the right schema is crucial to ensuring efficient storage, retrieval, and management of vast amounts of data. The Snowflake Schema, known for its normalized structure, offers several advantages that make it a compelling choice for certain use cases. Let’s explore the key benefits of the Snowflake Schema in data warehousing.

Normalization: Enhancing Data Integrity
The primary strength of the Snowflake Schema lies in its commitment to data normalization. By breaking down dimension tables into smaller, related tables, the schema minimizes data redundancy. This normalization process enhances data integrity, as information is stored in a structured and consistent manner. Reducing redundancy not only saves storage space but also ensures that updates or modifications to the data are made in a centralized location, maintaining a single version of the truth.
Maintenance Simplicity and Consistency
Modifying or updating a database schema can be a complex task, but the Snowflake Schema simplifies this process. Since the schema is broken down into smaller, interconnected tables, changes can be made in specific dimension tables without affecting the entire schema. This level of modularity ensures that maintenance tasks are more straightforward, and updates can be implemented with minimal impact on other parts of the database. This simplicity in maintenance contributes to a consistent and reliable data environment.
Scalability: Adapting to Growing Datasets
A normalized dimension can make shared attributes easier to maintain as a model grows. However, additional tables and joins can also increase complexity. Test refresh time and representative reports at the expected data volume before treating either design as the more scalable option.
Reduced Redundancy: Efficient Storage Utilization
Separating shared dimension attributes can reduce duplicated values and help keep updates consistent. It does not automatically make retrieval faster: reporting queries may need additional joins. Assess redundancy, query cost and maintenance together.
Support for Complex Relationships
In scenarios where data relationships are intricate and involve multiple dimensions, the Snowflake Schema shines. Its ability to break down relationships into smaller, manageable tables allows for the representation of complex hierarchies and relationships. This feature is particularly beneficial for industries or applications where understanding intricate data connections is essential, such as in hierarchical organizational structures or complex product hierarchies.
Advantages of Star Schema in Data Warehousing
The Star Schema stands as a prominent and widely adopted design in the field of data warehousing, known for its simplicity and efficiency. This schema model, characterized by a central fact table surrounded by denormalized dimension tables, offers several advantages that contribute to its popularity and effectiveness in analytical environments. Let’s explore the key benefits of the Star Schema.
Simplicity and Understandability
The primary strength of the Star Schema lies in its simplicity. The structure, featuring a central fact table and denormalized dimension tables, is intuitive and easy to understand. This simplicity is advantageous for both database designers and end-users. Designers can create and maintain the schema with ease, while end-users find it straightforward to navigate, fostering quicker comprehension and utilization of the data.
Query Performance
Direct relationships between the fact table and dimensions can make star-schema queries simpler. Fewer joins may help performance, but the result depends on the database engine, physical design, data size and reporting workload. Benchmark the actual queries rather than promising a fixed speed improvement.
Flexibility in Dimension Hierarchies
The Star Schema provides flexibility in representing dimension hierarchies. Each dimension table can be designed independently, allowing for the creation of various hierarchies based on business requirements. This flexibility is particularly beneficial in scenarios where diverse perspectives on the same data are necessary. It enables organizations to adapt the schema to changing analytical needs without disrupting the overall structure.
Ease of Maintenance
Maintaining the Star Schema is notably straightforward. Changes to the schema, such as the addition of new dimensions, can be implemented without affecting the existing structure significantly. This modularity simplifies maintenance tasks, reducing the risk of unintended consequences when modifications are made. The ease of maintenance ensures that the schema remains agile and responsive to evolving business requirements.
Scalability
Scalability is a crucial consideration in data warehousing, and the Star Schema performs well in this regard. As data volumes grow, the schema’s simple and denormalized structure allows for efficient scaling. The addition of new data does not inherently introduce complexity, ensuring that the schema can evolve with the organization’s data requirements over time.
Query Performance vs. Normalization
Choose a design by balancing reporting simplicity with the way dimension attributes are maintained. Normalization can organize shared attributes, while denormalized dimensions can simplify common analytical queries. Neither choice guarantees faster queries for every platform.
For a platform-specific example, read Microsoft Learn’s star-schema guidance. Power BI modeling decisions should account for relationship paths and the experience of report authors, not just the shape of the source database.
Flexibility vs. Consistency
Star Schema:
The Star Schema is known for its flexibility. New dimensions can be added without significantly altering the existing structure. This adaptability makes it well-suited for businesses with evolving requirements or those undergoing frequent changes in their analytical focus.
Snowflake Schema:
On the other hand, the Snowflake Schema prioritizes consistency and ease of maintenance. Changes to the database schema are more straightforward, typically requiring modifications in the affected dimension table without extensive adjustments elsewhere. This level of consistency is beneficial in scenarios where maintaining a stable and reliable data environment is paramount.
System Resources
A snowflake design can reduce repeated dimension attributes, but additional keys, relationships and tables also consume resources. A star design repeats some descriptive values, yet compression can reduce their storage cost. The database engine, model size and workload determine the practical storage and memory trade-offs. Measure query time, refresh time and model size on representative data.
Data Complexity and Relationships
Star Schema:
When dealing with relatively simple data relationships and structures, the Star Schema excels. Its straightforward design, with a central fact table and denormalized dimension tables, is well-suited for scenarios where data hierarchies and relationships are uncomplicated. If your data model can be represented with clear, singular dimensions, the Star Schema may streamline your analytical processes.
Snowflake Schema:
For organizations with complex data relationships and hierarchies, the Snowflake Schema offers a more granular approach. By breaking down dimension tables into normalized structures, intricate relationships can be represented accurately. This is particularly valuable in industries where understanding complex relationships, such as organizational hierarchies or product categorizations, is essential.
Data Modification Frequency
Frequent changes do not automatically make a star schema preferable, and infrequent changes do not automatically favor a snowflake schema. Consider where attributes are shared, how updates are loaded and whether historical versions must be preserved. Test both ordinary updates and late-arriving records with the chosen key and history rules.
Compatibility with BI Tools
Star Schema:
The simplicity of the Star Schema often aligns well with various analytical tools and platforms. Many business intelligence and reporting tools are optimized for star-like structures, making it easier to integrate the schema into existing analytics ecosystems.
Snowflake Schema:
While Snowflake Schema compatibility with tools has improved, some analytical tools may require additional configuration or optimization to work seamlessly with the normalized structure. Organizations should consider the compatibility of their preferred analytics tools when choosing between Snowflake and Star Schema.
User Expertise and Training
Star Schema:
The straightforward nature of the Star Schema makes it easier for end-users to understand and navigate. If your organization has a user base that may not be well-versed in complex database structures, the simplicity of the Star Schema could lead to quicker user adoption and reduced training requirements.
Snowflake Schema:
The normalized structure of the Snowflake Schema may require more expertise to navigate, especially for users unfamiliar with database normalization concepts. Organizations should assess the level of expertise within their user community and provide adequate training if opting for the Snowflake Schema.
What is the main difference between a star and snowflake schema?
A star schema keeps dimension attributes together in denormalized dimension tables. A snowflake schema splits dimension attributes into related, normalized tables. Both connect descriptive data to measurable facts.
Is a snowflake schema the same as the Snowflake platform?
No. A snowflake schema is a data-modeling pattern. Snowflake is a cloud data platform. You can implement different modeling patterns on a platform; the similar name does not require one particular design.
Which schema is easier for beginners to understand?
A star schema is usually easier to follow because dimensions connect directly to the fact table. Start by defining what one fact row represents, then identify the dimensions needed to explain it.
Does a star schema always run faster?
No. Fewer joins can simplify a query, but speed also depends on the database engine, data volume, physical design, caching and query shape. Compare both designs using representative queries before choosing.
Does a snowflake schema always use less storage?
No. Normalizing attributes can reduce repeated dimension values, but extra keys, tables and relationships also have a cost. Compression and the storage engine can change the result. Measure the model you actually use.
Can both schemas keep historical dimension changes?
Yes. History depends on your loading and versioning rules, not just the schema shape. For example, a customer address can be overwritten when only the latest value matters, or versioned when historical reporting needs it.
What is a simple example of the two designs?
For sales reporting, a star product dimension might hold product, subcategory and category together. A snowflake design can separate product, subcategory and category into related tables while retaining a sales fact table.
How should I choose a schema for a project?
Write down the reporting questions, data grain, expected size, update process and users. Build a small working model, check correct totals, then compare query time, refresh time and maintenance effort.
How do I check that changing the schema preserves results?
Run the same reports before and after the change. Compare row counts, totals and distinct keys. Test missing dimension values, duplicate keys and historical changes so joins do not silently drop or multiply facts.
What should I explain in a data-modeling interview?
Explain the grain of the fact table, dimension keys, normalization choice and expected reporting workload. Describe a trade-off and a test you would run. Avoid claiming that one design is always faster or better.
Brolly Academy | Snowflake Guides
Snowflake Schema vs Star Schema
Same facts. Different dimension structures.
Both patterns organise facts and dimensions. The key difference is whether a dimension stays in one wider table or is split into related tables.
Choose a design by balancing reporting simplicity with the way dimension attributes are maintained.
Share
- Nani
- Brolly Academy
- 10 min read (estimated)
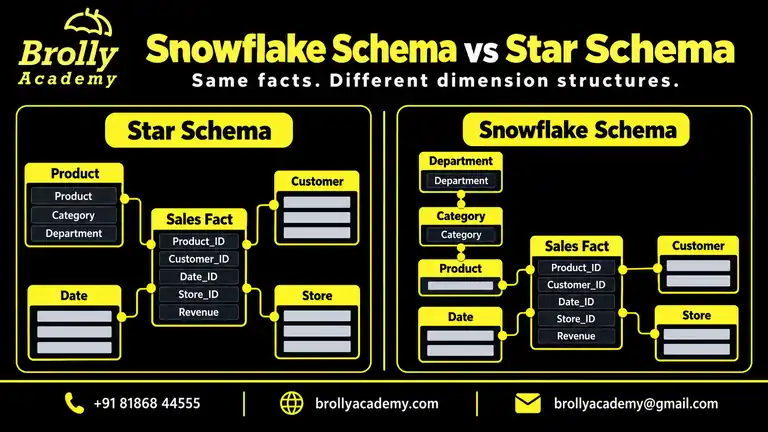
Table of Contents
Related Articles
Explore facts, dimensions and normalized dimension hierarchies.
Explore the storage, compute and cloud services behind Snowflake workloads.
Explore Snowflake platform capabilities, workflows and use cases.
Related Courses
Explore the Snowflake course, practical learning topics and available training formats.
Explore data integration, orchestration and cloud pipeline training.